How to Probe Network Services with Blackbox Exporter
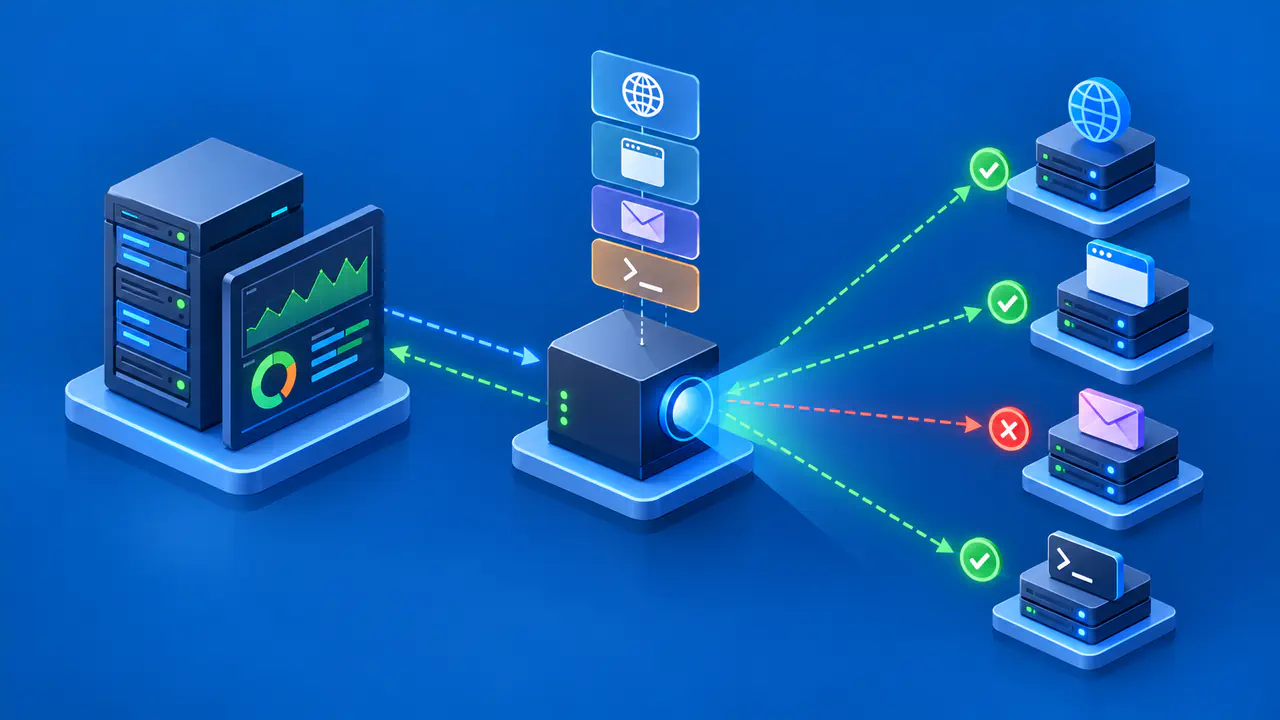
Blackbox Exporter measures a network service from the outside by sending a probe and exposing the result to Prometheus. An HTTPS response, DNS answer, TCP connection, or ICMP echo reply shows what is reachable from the machine running the exporter. These probes complement application metrics; they do not report host interface counters or explain every internal cause of a failure.
Set up probes only for services and networks you are authorized to test. If the probe endpoint is publicly accessible, an outside caller may be able to make the exporter contact internal addresses. Limit access to the exporter and choose the targets you intend to monitor before configuring recurring scrapes.
Choose Modules and Authorized Targets
A module defines how Blackbox Exporter probes a target. HTTP and HTTPS use the HTTP prober; DNS, TCP, and ICMP have their own probers. Match the module to what you need to check: an HTTP check can evaluate a web response, a TCP check can establish whether a socket accepts a connection, a DNS check can ask a resolver a specific question, and ICMP checks reachability with echo requests.
A successful TCP connection does not prove the application protocol works, and an ICMP failure does not prove an HTTP service is down if echo is filtered.
Write a short target inventory with the service owner, expected address and port, probe location, module, and expected success condition. For HTTP, decide whether redirects, status codes, TLS, or response body content matter. For DNS, identify the resolver and query you intend to check. For TCP, choose the exact host and port. Avoid probing third-party endpoints at an aggressive interval just because they are reachable.
Configure Blackbox Exporter
Install a current Blackbox Exporter release for your operating system and processor. The commands below assume the Linux binary is in the current directory and Prometheus runs directly on the same machine. Create blackbox.yml with four modules:
modules:
  web_check:
    prober: http
    timeout: 5s
  dns_check:
    prober: dns
    timeout: 5s
    dns:
      query_name: example.com
      query_type: A
      valid_rcodes: [NOERROR]
  tcp_check:
    prober: tcp
    timeout: 5s
  ping_check:
    prober: icmp
    timeout: 5s
Replace example.com with the name you want the DNS server to resolve. The DNS target will be the server's address, supplied separately; the query asks that server for an A record for the specified name. The web module accepts successful 2xx responses by default, while the TCP module above checks only whether a connection can be established.
Check the configuration with ./blackbox_exporter --config.file=blackbox.yml --config.check. If validation succeeds, start the exporter with ./blackbox_exporter --config.file=blackbox.yml --web.listen-address=127.0.0.1:9115. The explicit bind address keeps this example accessible only through the machine's IPv4 loopback interface.
ICMP needs additional operating system permissions. On Linux, the exporter must run with a group allowed by net.ipv4.ping_group_range, the CAP_NET_RAW capability, or root privileges; choose the least privileged option that works for the deployment. Windows requires Administrator privileges for ICMP probing.
Try a Probe before Scheduling It
Use one working target and one deliberately failing target that you control. For an HTTP check, run the following command from the exporter machine, replacing the example URL with the authorized target:
curl --get --data-urlencode "target=https://example.com/" --data-urlencode "module=web_check" http://127.0.0.1:9115/probeThe response contains metrics for that request. Check that the working target succeeds and the failing target fails for the intended reason. Adding --data-urlencode "debug=true" to the command includes diagnostic details; use that mode for investigation, not as the response Prometheus scrapes.
Configure the Prometheus Scrape Jobs
Prometheus requests a probe from the exporter, which then contacts the target. The configuration below passes a different module for each target group and preserves the target address as the visible instance label. Replace the documentation addresses with your authorized endpoints and change the location label to identify this exporter:
scrape_configs:
  - job_name: network_probes
    scrape_interval: 30s
    scrape_timeout: 10s
    metrics_path: /probe
    static_configs:
      - targets: ['https://example.com/']
        labels:
          module: web_check
      - targets: ['203.0.113.53:53']
        labels:
          module: dns_check
      - targets: ['203.0.113.20:443']
        labels:
          module: tcp_check
      - targets: ['203.0.113.20']
        labels:
          module: ping_check
    relabel_configs:
      - source_labels: [__address__]
        target_label: __param_target
      - source_labels: [module]
        target_label: __param_module
      - source_labels: [__param_target]
        target_label: instance
      - target_label: probe_location
        replacement: lab
      - target_label: __address__
        replacement: 127.0.0.1:9115
  - job_name: blackbox_exporter
    static_configs:
      - targets: ['127.0.0.1:9115']
Add these two jobs to the existing scrape_configs list in prometheus.yml; do not create a second list with the same key. The relabeling rules copy the original address into the target parameter before replacing the scrape destination with the exporter address. Copying the module label into __param_module selects the matching module in blackbox.yml.
Both loopback addresses assume that Prometheus and the exporter share the same network namespace. If either runs in a separate container or on another machine, use an exporter address that Prometheus can reach and adjust the exporter's listener and access restrictions. The exporter also needs its own route to every target.
The second job requests the exporter's /metrics endpoint, which reports the exporter's operational metrics. A successful scrape there does not establish that a remote service probe works. Keeping both jobs makes the two kinds of result available for troubleshooting.
Run promtool check config prometheus.yml before loading the configuration. Reload Prometheus using the deployment's supported method; on Linux, sending SIGHUP to the Prometheus process reloads its configuration. Check the targets page for the expected jobs, module labels, target addresses, and scrape errors.
Read Success and Timing Metrics
For a successful scrape of /probe, probe_success is 1 when the selected probe succeeds and 0 when it fails. Inspect protocol-specific metrics and timing phases to understand whether the failure involves name resolution, connection setup, TLS, transfer, or an unexpected response. For HTTP, probe_http_duration_seconds breaks the elapsed time into phases; probe_duration_seconds gives the total probe duration. Inspect the actual output because available measurements differ by protocol and version.
A slow probe that consumes most of its allowed timeout may deserve attention before it fails outright.
Set the Prometheus scrape interval and timeout with enough room for the probe. The exporter derives its time allowance from scrape_timeout, leaving a small margin, and also honors a shorter module timeout. In this example, a probe has a five-second module limit within a ten-second scrape timeout, with scrapes scheduled every thirty seconds.
A timeout too short for the intended service can create alert noise. A generous timeout may count an unacceptably slow response as successful, so alert on response duration separately where speed matters. Use separate scrape jobs when groups need different scheduling intervals.
Separate Probe Failures from Scrape Failures
When Prometheus collects a failed probe result, the probe job's up series is 1 while probe_success is 0. The exporter answered the scrape, but the target did not meet the selected module's success conditions. The cause could be the service, the network path, or an unsuitable module setting.
If up is 0, Prometheus failed to scrape that endpoint and has no fresh probe result from the failed scrape. The exporter may be unreachable, but an invalid module name, a scrape timeout, or another response error can also cause this state. Check the scrape error and the separate exporter job before diagnosing an exporter outage.
For this configuration, probe_success{job="network_probes"} == 0 selects failed probes, while up{job="network_probes"} == 0 selects failed probe scrapes. Add a separate alert for up{job="blackbox_exporter"} == 0. Use a suitable for duration so the alert condition must persist through successive evaluations before the alert fires.
In a controlled test environment, compare the working and failing targets, then briefly stop the exporter and observe the difference. Confirm that alerts identify the target and probe location and that stopping the exporter triggers the expected scrape alert. Restore the exporter after the test.
Limit Exposure and Alert Noise
Bind or firewall the exporter so only Prometheus and authorized operators can call /probe. Restrict outbound reachability where practical and avoid putting credentials or sensitive query strings into target labels. Review redirects because an HTTP probe may follow a new destination.
Use thresholds appropriate for each service and silence planned maintenance alerts for the affected targets. Keep the target list, module names, and expected behavior documented as services change.