What Is IP Reputation?
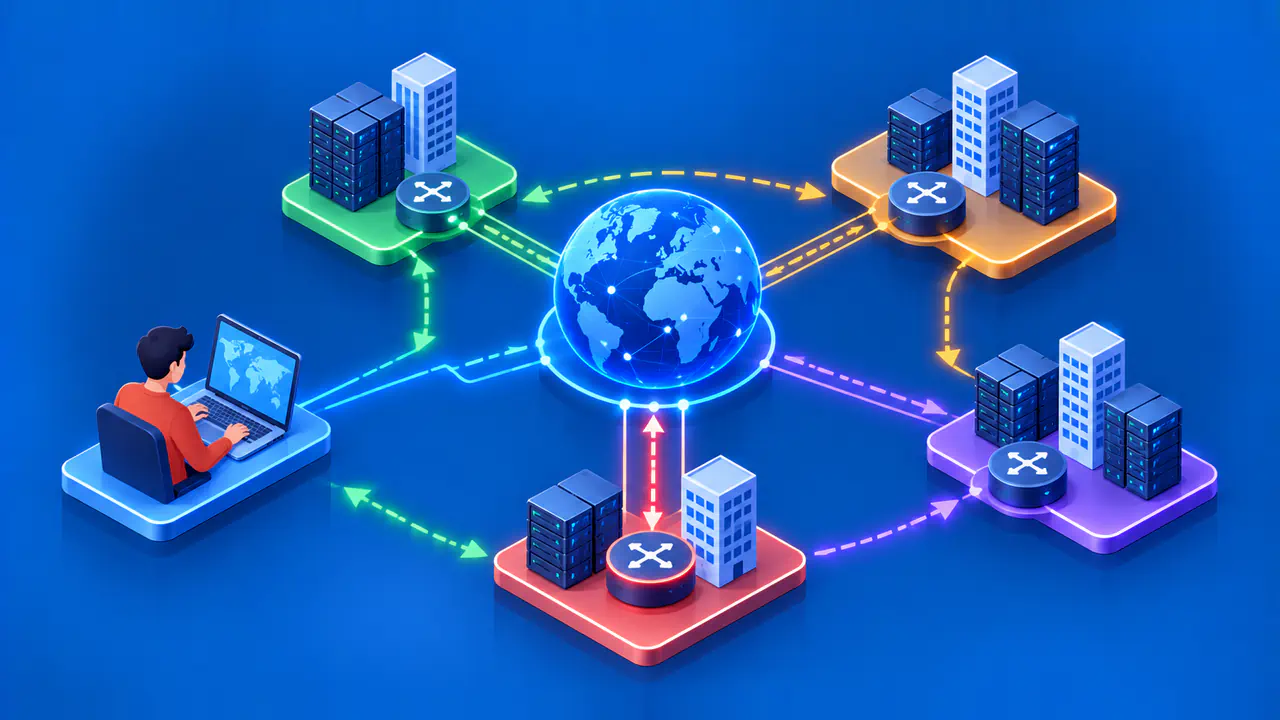
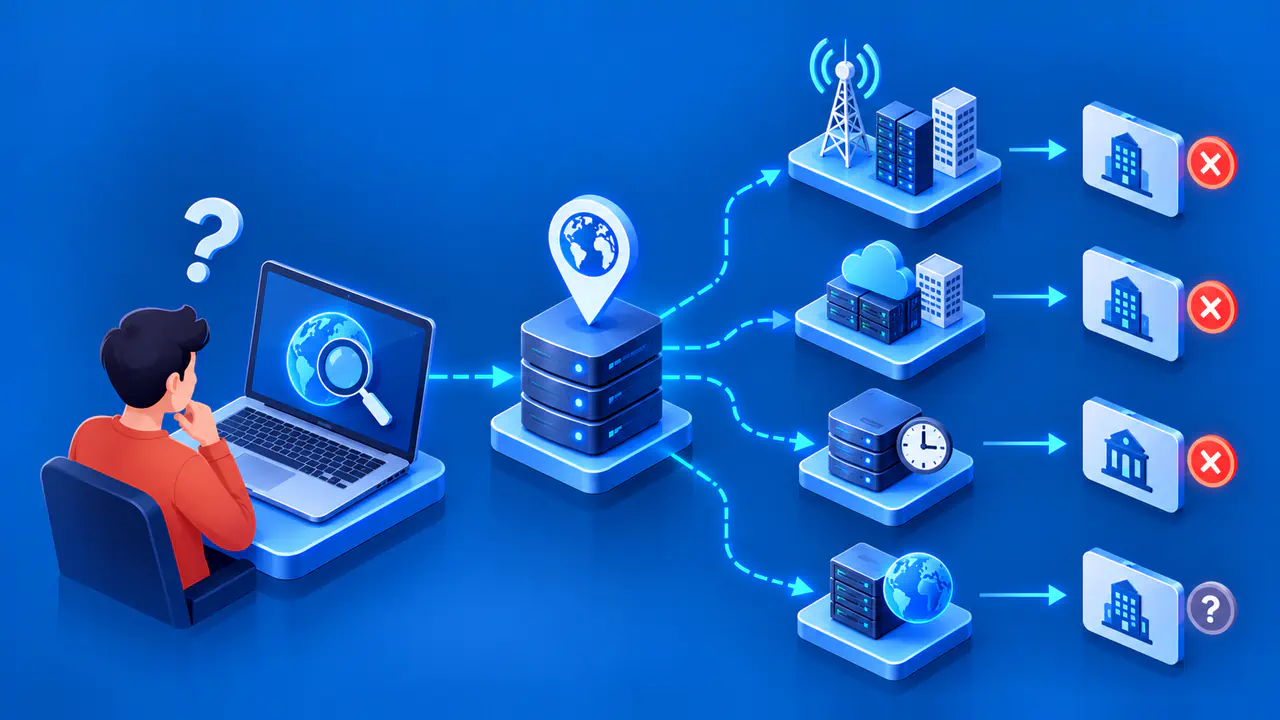
IP reputation is an assessment of an IP address or network used to help decide how to handle traffic. A company that supplies reputation data may publish a blocklist, assign a category, or calculate a risk score. A receiving mail server or website then decides how to use that information. There is no single worldwide score that every service follows.
An IP address does not identify a unique person. Several people can share one public address, and an internet service provider can reassign an address to a different customer. A reputation result may therefore reflect activity unrelated to the person using the address now. Understanding the result means checking who produced the data, what the label means, and how the service applied it.
How IP Reputation Is Assessed
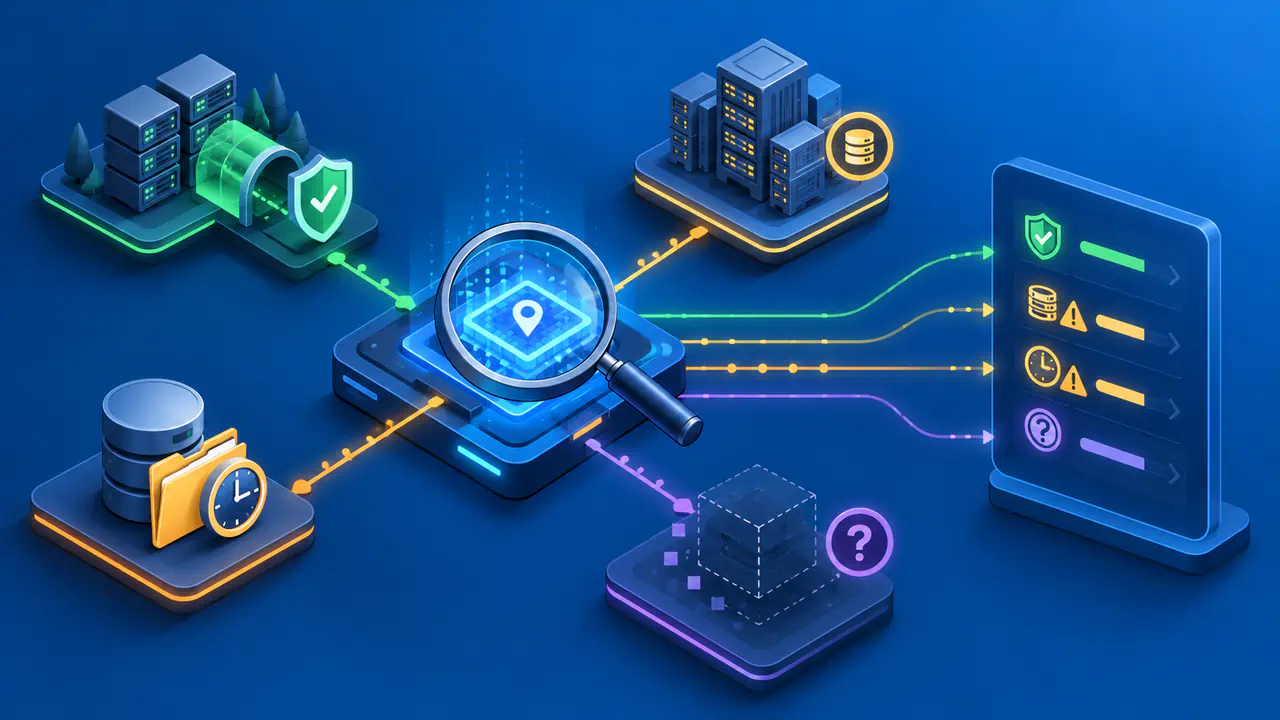
Reputation data can come from observed traffic, abuse reports, network classifications, or policies about how addresses should be used. Those sources answer different questions. Evidence of spam sent from an address describes observed activity, while a policy list may simply identify addresses that should not send mail directly to recipients' servers. Neither result should be interpreted without the list's definition.
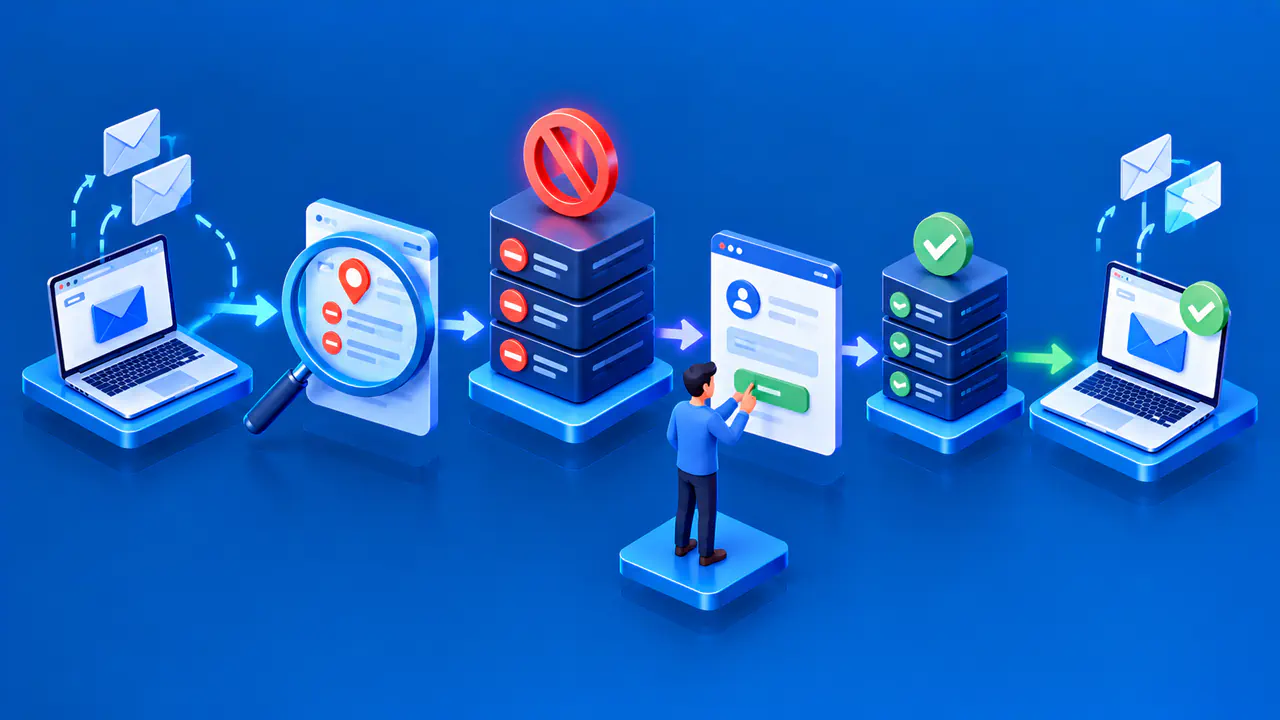
For example, the Spamhaus Policy Blocklist includes address ranges where direct delivery to recipient mail servers is not permitted under the relevant sending policy. Other Spamhaus lists cover spam sources or compromised systems. A receiving server can reject a message based on a listing or accept the message for further filtering. The list supplies information, while the mail operator chooses the action.
Network categories need similar care. A VPN or hosting flag identifies a type of connection, not an observed abusive act. MaxMind's Anonymous IP database, for example, distinguishes VPNs, hosting networks, public proxies, Tor exit nodes, and suspected residential proxies. A website can use those categories in an access rule, but a category alone does not establish why a particular visitor connected.
A numerical result also needs a definition. Check what the score estimates, whether a higher value means more risk, and which traffic or observations contribute to it. Two products can use different scales or assess different kinds of activity. Matching numbers do not make their conclusions equivalent, and a score useful for one service may be irrelevant to another.
Why Shared Addresses Affect Reputation
Home routers, workplace networks, public Wi-Fi, and carrier-grade network address translation (CGNAT) can let several users reach the internet through one public IPv4 address. If a service blocks that address after one user's activity, unrelated users can lose access too. The service sees the shared source address even though the requests came from different devices or customers.
Reassignment creates a different problem. An address previously associated with unwanted traffic may later be assigned to a customer whose connection has no such history. If the reputation data has not caught up, the new customer can encounter restrictions based on earlier use. A current lookup does not reveal who held the address when an old event occurred.
These cases limit what can be inferred from an address alone. An investigation may need the event time and additional connection records to distinguish users behind a shared address. A general reputation lookup does not provide that attribution. Avoid treating an address-level label as proof about a named person or a particular device.
When a Reputation Result Covers a Network
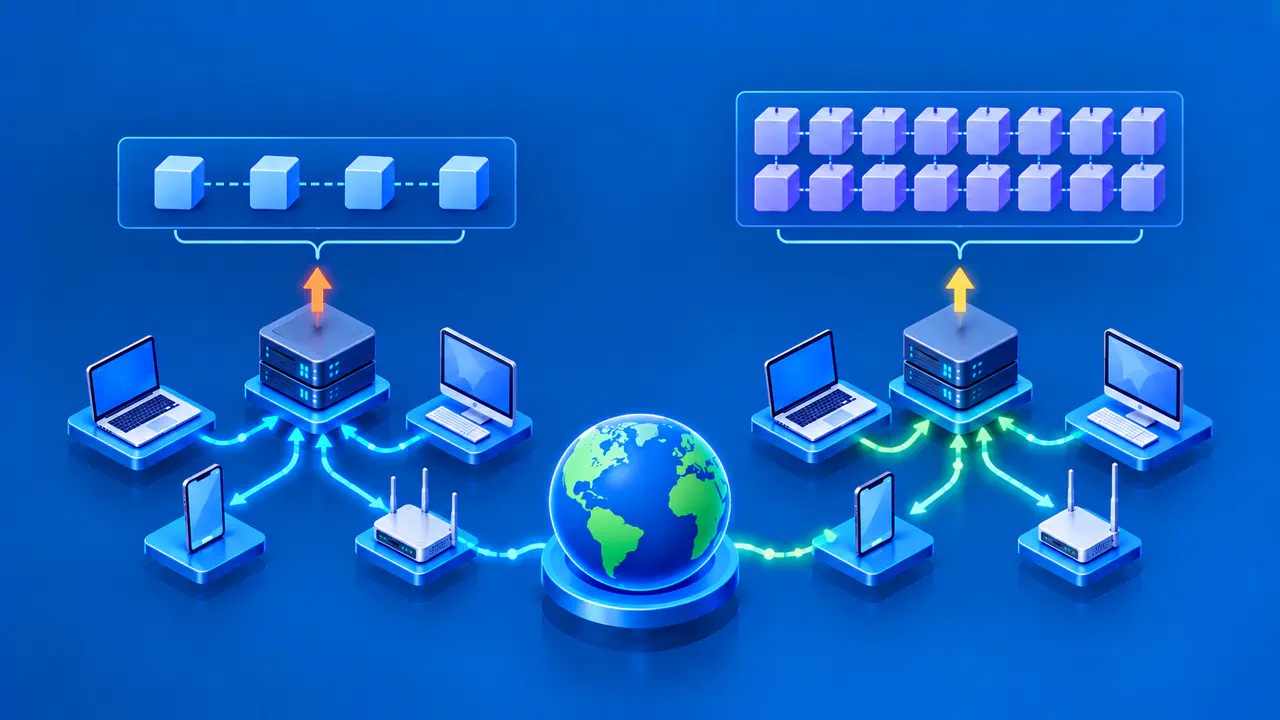
Some results apply to one address, while others describe a range containing many addresses. Such a range may be written as a network prefix using CIDR notation, with a slash followed by the number of bits that identify the network. Check the matched range before assuming that the data describes only the exact address you entered.
For example, records in MaxMind's Anonymous IP database include an IPv4 or IPv6 network in CIDR notation. Each record can associate a category with a block of addresses. The presence of a network field does not mean that every reputation product uses the same grouping or assigns the same risk to every address in that block.
IPv6 makes this distinction especially important because a network can contain many changing device addresses. A data product might assess individual addresses, aggregate observations for a prefix, or supply both kinds of information. There is no universal IPv6 prefix length for reputation scoring. A /64 grouping used for an estimated user-count field, for example, does not establish the unit used for an unrelated risk score.
A clean result for one address also says nothing definite about a separate range-based rule. If a service reports that a network is restricted, identify the prefix it matched and the rule that used that prefix. Checking a different address without checking the range can produce an apparently contradictory result that actually concerns different data.
Why Reputation Labels Can Be Wrong
A reputation result can become outdated after an address changes hands or a network changes how it is used. Data may also be classified incorrectly in the first place. Keep those possibilities separate from a service making an overly broad decision using accurate data. A correct VPN category, for instance, does not justify describing every visitor from that network as abusive.
The wording of a result helps distinguish these problems. An ISP name identifies an internet service provider, a hosting flag describes a network category, and an abuse-related entry records a different kind of information. Combining those fields into a single description such as “bad IP” hides the actual reason for concern. Compare the service's stated reason with the definition of the field or list involved.
Timing matters when comparing results. A lookup performed today may use newer data than the service used when it rejected a request. Record the address, the time of the refusal, the exact error message, and the data provider or list named in that message. A later lookup can help explain the situation, but it cannot reconstruct an earlier decision by itself.
What a Reputation Result Can Tell You
A reputation lookup can show how a particular data source classifies an address at the time of the query. It cannot, on its own, establish the reason for every blocked page or rejected message. A service may combine reputation data with account restrictions, request patterns, or its own access rules. An address can be absent from the source you checked and still be refused by a service.
For a rejected email, start with the delivery error and any blocklist named there. For a website restriction, use the displayed error and the site's support guidance to identify the rule involved. If you cannot tell which data source the service used, another lookup site's score may have little bearing on the refusal.
When the evidence points to inaccurate data, the data supplier's review process may be relevant. When accurate data has been applied too broadly, the service using that data controls its own rule. The appropriate contact and available review options depend on the product and service involved. Correcting a record in one database does not automatically change an independent service's decision.